Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The Numbers That Matter

Let’s start with the thing that makes purists nervous and pragmatists sit up straight: the Linux kernel now contains over 600,000 lines of Rust code. That’s not a typo. We went from roughly 13,000 lines when Rust support officially merged in kernel 6.1 back in late 2022 to more than 600,000 lines by early 2026. If you’ve been half-paying attention to the kernel mailing list drama, you know that trajectory should feel impossible. And yet here we are.
Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The acceleration matters because it suggests something shifted from “interesting experiment” to “structural inevitability.” When a change compounds that fast in a codebase as conservative as the Linux kernel, it’s not hype driving it. People building real systems started actually using it. That’s the signal buried under the noise of the debates.
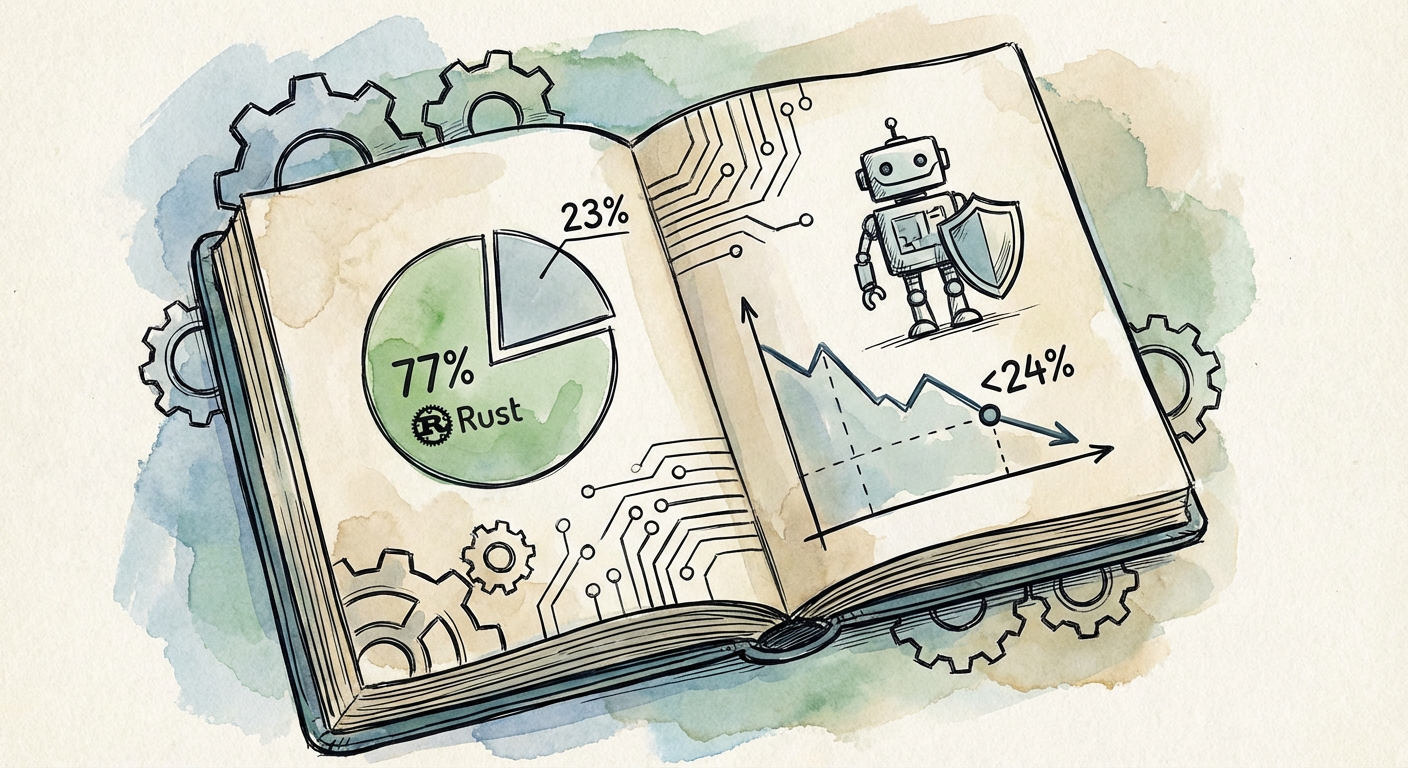
Illustration for Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The Debate You Probably Missed (But Should Care About)

The mailing list drama in late 2025 crystallized around something deceptively simple: are Rust abstractions in the kernel hiding performance problems? Ted Ts’o, a veteran C maintainer whose opinions carry weight precisely because he doesn’t throw them around, posted a detailed technical critique arguing that Rust’s abstraction layers were creating subtle performance regressions in I/O paths that conventional benchmarks weren’t capturing. It wasn’t ideological. It was granular. It was the kind of argument that makes you actually look at the generated assembly.

What made it interesting rather than just another flame war: the response wasn’t dismissal. Contributors started digging. Some benchmarks got re-run. Some abstractions got revisited. This is how good kernel development actually works, even when people disagree sharply. The conversation proved something important about the Rust-in-kernel community: it has enough technical maturity to argue about second-order effects instead of first principles.

The Security Data That’s Actually Compelling

A 2025 study from the University of Waterloo analyzed 150 kernel CVEs from the 2020-2024 window and found that 67% fell into memory safety categories that Rust’s ownership model structurally prevents. That’s not hypothetical. That’s forensic. Two-thirds of the vulnerabilities that people actually exploited in the real world vanish as a category if you write the code in Rust instead of C.

The Android team put real numbers on what that means operationally. Google Security Blog on memory safety in Android reported that the proportion of new Android OS code written in memory-safe languages reached 77%, with Rust accounting for most systems-level additions. Memory safety vulnerabilities in Android dropped to below 24% of total CVEs for the first time. That’s not a marginal improvement. That’s a genuine shift, and it happened because they made a deliberate technical choice and stuck with it.

Where the Real Work Lives Now

Linus confirmed in December 2025 that Rust driver contributions accelerated significantly. The highest-profile all-Rust driver effort to date is the Nova GPU driver for NVIDIA open-source firmware. This matters because drivers are where abstraction layers meet real hardware constraints. If Rust works there at scale, it works. The Nova driver isn’t toy code. It’s addressing a genuine gap in the open-source graphics stack.

The Linux kernel Rust documentation has matured into something you can actually follow without maintaining a mental model of the entire language ecosystem. Less “here’s why we’re doing this philosophically,” more “here’s how you abstract a spinlock, here’s what the borrow checker wants from your IOMMU binding.” The documentation gap was real, and watching it close is genuinely satisfying if you’ve worked in system-level code long enough to appreciate the friction it reduces.

What This Actually Signals

The kernel mailing list drama tells you something important if you know how to read it: the Rust transition isn’t being imposed from above. It’s emerging from below. Driver maintainers are adopting it. Security teams are seeing the empirical gains. The abstractions are getting better because people who understand kernel internals are building them, not language designers guessing at what the kernel needs.

The remaining friction isn’t ideological purity on either side anymore. It’s genuinely hard technical questions about performance visibility, compile-time overhead, and how you teach people who’ve spent two decades reasoning about C memory models to reason about ownership instead. Those are solvable problems. They’re engineering, not philosophy.

If you’ve been sitting on the sidelines treating Rust in the kernel as theater, this is the moment to actually look at what’s shipping. The numbers have crossed a threshold. The security data is credible. The code is real. This isn’t speculation about the future anymore. What do you see when you actually dig into it?
Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The Numbers Tell a Story Worth Reading

If you’ve been paying attention to kernel development over the past eighteen months, you’ve noticed something odd. The Rust-in-the-kernel conversation shifted. It stopped being theoretical. Around early 2026, the Linux kernel crossed a threshold that makes it impossible to dismiss Rust as an experiment anymore: over 600,000 lines of Rust code, spread across drivers, filesystem abstractions, and core subsystem bindings. That’s not a rounding error. That’s not a proof of concept someone’s uncle wrote in a weekend. That’s infrastructure.

Remember when this all started? Kernel 6.1, late 2022. We got roughly 13,000 lines of Rust. Everyone held their breath. The skeptics dusted off their keyboards. The enthusiasts refreshed their RSS feeds hourly. Four years later, we’ve grown that initial footprint by a factor of more than forty. The acceleration itself is the story here, because acceleration in the kernel means something. It means maintainers are buying in. It means the friction isn’t theoretical anymore—it’s either real and being solved, or it never was.

Why the Mailing List Fights Actually Matter

The kernel mailing list has always been where the real work happens. It’s adversarial by design. People yell at each other with genuine technical conviction. That’s not a bug, it’s the feature that keeps bad ideas from shipping. So when you see threads exploding about Rust abstractions in 2025, when a veteran like Ted Ts’o posts detailed technical critiques about hidden performance regressions in I/O paths that benchmarks aren’t catching, that’s not noise. That’s the immune system working.

Ts’o’s specific concern about compile-time complexity creating subtle performance degradation is the kind of thing that matters precisely because it’s not obvious. You can run your benchmarks. Everything looks fine. But then in production, under specific workload patterns, something feels off. The margin between good and great in kernel code is often measured in basis points. When someone with his track record flags a concern, the appropriate response isn’t dismissal. It’s investigation. And it’s happening.

What’s genuinely interesting is that these aren’t debates about whether Rust belongs in the kernel anymore. Those debates happened. They’re settled. This is debugging. This is engineering. This is the hard part that comes after you’ve won the philosophical argument.

The Evidence Actually Backs the Move

Here’s where the pedantic engineer in me gets genuinely excited. A 2025 study from the University of Waterloo took 150 kernel CVEs from the 2020-2024 window and categorized them. Sixty-seven percent fell into memory safety categories that Rust’s ownership model structurally prevents. Not all. Not ninety-five percent. But two-thirds. That’s not some aspirational number that lives in promotional material. That’s real vulnerability data.

Think about what that means in practical terms. If you’re a security engineer responsible for auditing kernel code, Rust doesn’t eliminate your job. But it fundamentally changes the class of bugs you need to worry about. You’re not hunting use-after-free bugs that mysteriously appear because someone forgot they had a shared reference. You’re hunting logic errors. That’s a better problem to have.

The smartphone evidence is even starker. Google’s Android team published numbers showing that memory safety vulnerabilities dropped below twenty-four percent of total CVEs for the first time, while the proportion of new OS-level code written in memory-safe languages hit seventy-seven percent. Most of that is Rust. That’s not an experiment in a lab. That’s what happens when you take memory safety seriously at the platform level. The vulnerabilities don’t disappear, but the low-hanging fruit evaporates.

The Real Inflection Point: GPU Drivers and All-Rust Subsystems

The moment that proved this stopped being academic was when Linus confirmed accelerating Rust driver contributions in a December 2025 mailing list post. But the real headline was the Nova GPU driver for NVIDIA’s open-source firmware. An all-Rust driver for modern graphics hardware. You know what that means? It means someone trusted Rust enough to handle the complexity of GPU command streams, memory management for discrete hardware, and real-time constraints. That’s not a filesystem abstraction. That’s not a wrapper around existing C code. That’s core driver logic where one mistake can hang the system or corrupt state catastrophically.

The existence of Nova isn’t proof that Rust is ready for everything. It’s proof that Rust is ready for hard problems. When the NVIDIA open-source team decides their GPU driver is easier to maintain and less likely to have security issues in Rust than in C, they’re making an economic bet. Economics wins kernel adoption. Ideology doesn’t.

What Comes Next in the Noise

The next five years are going to be messy. The abstractions will get refined. The performance concerns will either disappear or become known constraints we accept. The tooling will get better. New problems will emerge that nobody anticipated. Linus will probably send an angry email about something. The maintainers will have strong opinions. This is normal.

If you’re following this from the outside, stop waiting for the verdict. The verdict is already in. Sixty-seven percent of historical CVEs prevented by design. Seventy-seven percent of new Android code in memory-safe languages. Over 600,000 lines of production Rust in the kernel right now. These aren’t hypotheticals anymore. If you want to understand where systems programming is heading, you need to understand Rust and you need to understand why the people making these decisions are making them.

Start with the Linux kernel Rust documentation. It’s dense, but it’s honest. Then go read Google Security Blog on memory safety in Android. Not because you need to agree with every decision, but because understanding the reasoning behind these decisions is how you figure out what’s coming next. The mailing list drama isn’t noise. It’s documentation. And right now, the documentation says memory safety at scale works when you design for it from the beginning.

The Terraform Fork Is Actually Winning Now: Why OpenTofu 1.9 Matters for Your Career

The Terraform Fork Is Actually Winning Now: Why OpenTofu 1.9 Matters for Your Career

The License Shock That Started Everything

In August 2023, HashiCorp did something that still makes seasoned infrastructure engineers wince. They yanked Terraform’s license from the permissive Mozilla Public License 2.0 and slapped on the Business Source License 1.1. If you weren’t paying attention at the time, that was the moment the community collectively held its breath and asked: “Wait, can they actually do that?” They could, and they did.

The Terraform Fork Is Actually Winning Now: Why OpenTofu 1.9 Matters for Your Career

What followed was textbook open-source friction. The Linux Foundation backed a fork. Contributors scattered. Management had to have uncomfortable conversations with procurement teams. For those of us who’d spent years building Terraform into production bedrock, it felt like finding out your most reliable tool came with invisible strings attached. The fork wasn’t some niche rebellion either. By the time the Linux Foundation OpenTofu project page went live, you could feel the gravitational shift.

Illustration for The Terraform Fork Is Actually Winning Now: Why OpenTofu 1.9 Matters for Your Career

OpenTofu 1.0 Was Just the Baseline, Not the Finish Line

When OpenTofu hit 1.0 stable in January 2024, plenty of people wrote it off as “just another fork.” Those people weren’t paying close attention. Yes, 1.0 meant feature parity with Terraform’s corresponding release. Yes, migration paths were smooth. But parity is not a strategy. It’s a starting point.

The real inflection came six months later when OpenTofu 1.8 shipped with native provider-defined functions. This wasn’t some cosmetic enhancement. This was the community delivering something Terraform users had literally begged for years, while HashiCorp kept it parked in the roadmap backlog indefinitely. Suddenly the fork wasn’t just catching up. It was pulling ahead. That matters psychologically in ways executives and boards understand: it means the fork has become the place where innovation actually happens. For engineers evaluating infrastructure tools in 2025, that’s not a minor distinction.

IBM Changed the Equation, IBM Didn’t Solve It

Then IBM acquired HashiCorp for approximately 6.4 billion dollars in mid-2024. This should have been reassuring. Established enterprise company. Deep pockets. Mature go-to-market infrastructure. Instead, it added fuel to the fire. The post-acquisition product roadmap updates landed with a thud. They didn’t address the fundamental anxiety: would HashiCorp, now an IBM property, become even more aggressive about monetizing something that had been free and open? Would the BSL expand to more products? The answers came back as eloquent silence.

From a career intelligence standpoint, this matters enormously. When your organization’s infrastructure automation engine is controlled by a vendor whose parent company has a track record of aggressive licensing, you’re now playing a different game. You’re not just managing infrastructure. You’re managing vendor risk. That’s a conversation your CTO is having with legal, and it creates real urgency around migration decisions.

The Migration Is Quietly Happening at Scale

Here’s where things get interesting for your 2025 calculus: a Spacelift survey from Q4 2024 found that 38% of organizations running Terraform were actively evaluating or had already moved to OpenTofu. Cost and license uncertainty were cited as primary drivers by 91% of respondents. Nearly four in ten shops have made a conscious choice to either jump or seriously prepare to jump.

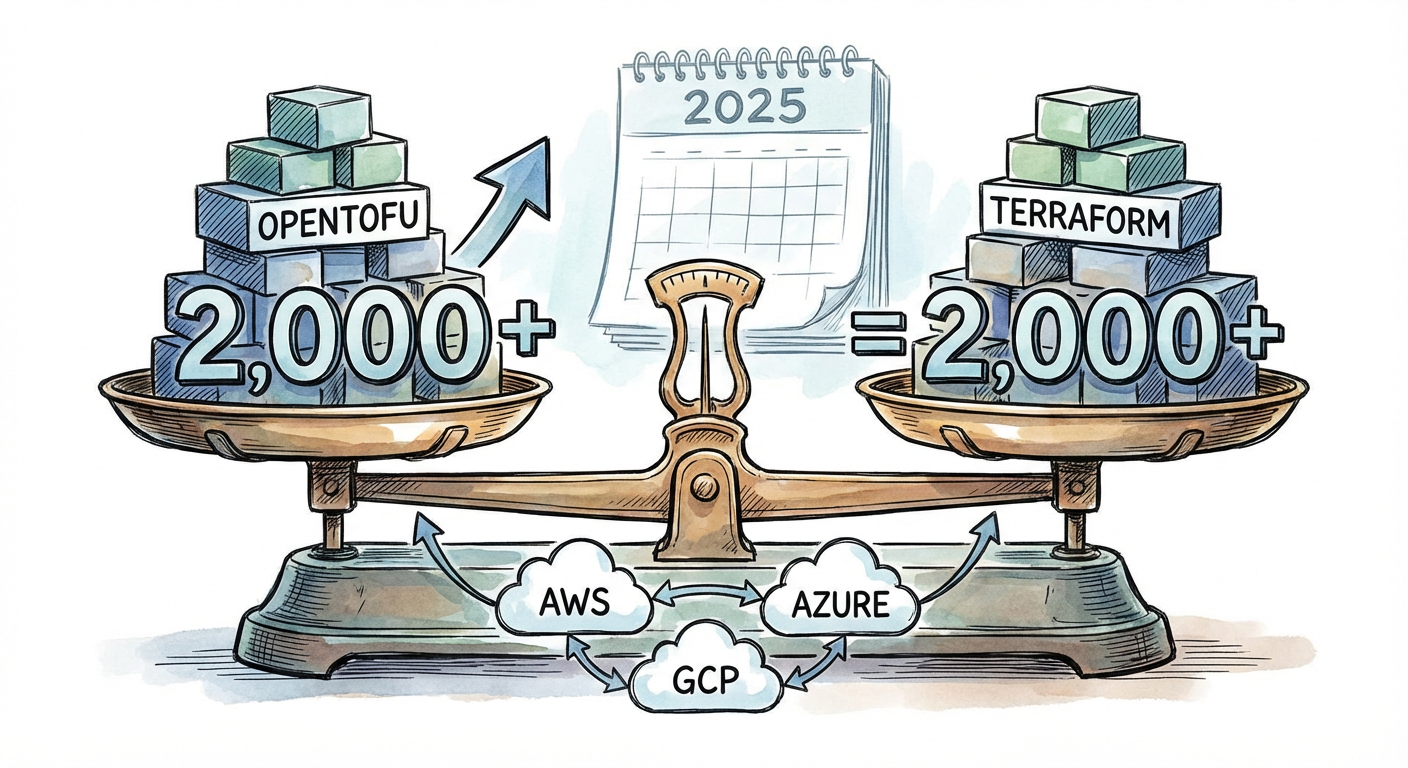
The OpenTofu registry has crossed 2,000 mirrored providers as of early 2025. That sounds like a number, but operationally it means something concrete: if you’re running AWS, GCP, and Azure infrastructure, you have functional parity with the Terraform Registry for virtually all your use cases. The ecosystem isn’t fragmented. It’s mature. The fork is no longer a gamble. It’s a legitimate alternative with real infrastructure behind it. Check the OpenTofu official documentation and changelog if you want granular details on what 1.9 adds, but the high-level story is that the project is shipping features and maintaining quality at a pace that makes platform teams take it seriously.

What This Means for Your Next Career Move

If you’re in infrastructure engineering, this inflection point matters. Organizations that migrated early to OpenTofu, or are actively planning to, tend to signal a few things: technical leadership willing to make independent tooling decisions, comfort betting on community-backed projects, and actual consideration of long-term vendor risk rather than just immediate convenience. Those are signs of mature engineering culture.

Conversely, shops that are still fully committed to Terraform because “that’s what we’ve always used” haven’t actually made a decision. They’ve just deferred one. Six months from now, your company will either be migrating, have migrated, or will be explaining to the board why migration isn’t on the roadmap. Worth understanding before you accept an offer or commit to a multi-year platform initiative.

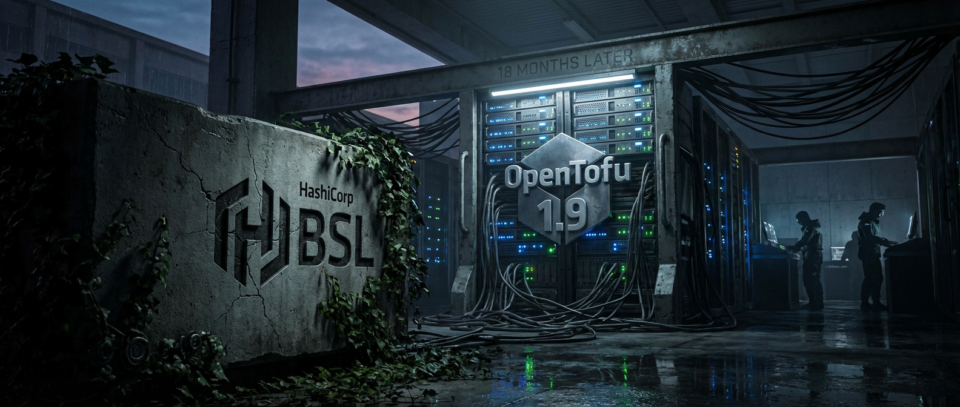
The pragmatic move? Get hands-on with OpenTofu 1.9 in a sandbox. Build something real. Walk through the migration path for your own infrastructure. Form your own opinion instead of inheriting someone else’s. You don’t have to decide which tool your organization should standardize on. But you should understand why, 18 months after a contentious fork, the minority tool is winning migration conversations at scale. That kind of technical pattern recognition makes you the person in the room who sees around the corner. That’s what careers are actually built on.

Platform Engineering Is Eating DevOps: What Backstage 2.0 and Internal Developer Portals Actually Look Like After the Hype

The Structural Shift Nobody’s Talking About Clearly Enough

DevOps, as a unified discipline, is dead. Not in the dramatic sense where something catches fire. More like how your favorite dive bar gets renovated into a gastropub. It’s still there, but the function has fundamentally changed.

What killed it wasn’t incompetence or bad tooling. It was success. As organizations scaled past a few hundred engineers, the old model of “DevOps handles infrastructure, developers just commit” stopped working. You can’t have six DevOps people managing the deployment pipelines for two hundred developers without everyone losing their minds at 2 AM. So organizations did what made sense: they hired more people focused specifically on making developers faster. That’s platform engineering, and it’s now the structural default at serious companies.

The numbers tell a story worth sitting with. In 2023, 43% of organizations with over 500 engineers had dedicated platform teams. By the end of 2024, that number jumped to 61%, according to the CNCF Annual Survey 2025. This isn’t a trend anymore. It’s a migration. Gartner is predicting that by 2026, 80% of large organizations will have platform engineering teams. If you’re reading this in mid-2026, you already know how that forecast landed.

Backstage 2.0: From Promising Tool to Actually-Solving-Problems Tool

Spotify’s Backstage hit 30,000 GitHub stars and crossed 3,000 production adopters by the end of 2025. Those aren’t vanity metrics. Three thousand companies running something in production means you have real feedback loops. Real complaints. Real problems that actually matter.

The version 1.x era of Backstage was brilliant but frustrating. Like having a Ferrari engine you had to assemble yourself. Powerful? Absolutely. Out of the box? Not remotely. Organizations loved the concept of a unified developer portal but struggled with the security model and had no good way to let AI tools integrate meaningfully without building custom plugins that broke on every upgrade.

Backstage 2.0, announced at KubeCon NA 2025, solved the two biggest enterprise adoption blockers. First, a new plugin permissions framework that actually lets you say “this plugin can read catalog metadata but not touch secrets.” Revolutionary? No. Necessary? Absolutely. Second, native AI assistant integration. Suddenly your portal can help onboard developers, explain service dependencies, and suggest deployment strategies without maintaining a parallel custom integration. Check the Backstage project documentation and changelog for specifics on what that looks like in practice.

Here’s the thing that matters most though: these weren’t features the Backstage team invented in a vacuum. These were the top two complaints from production users. The project listened, shipped solutions, and now organizations that were on the fence have fewer reasons to build it themselves or pick something else.

What an Internal Developer Portal Actually Does (When It Works)

Let’s cut past the marketing language and talk about what a mature internal developer portal genuinely changes. A McKinsey study from late 2025 found that organizations with mature portals reduced developer onboarding time by 55% and decreased unplanned downtime incidents by 32%. Those numbers sound like they came from a sales deck, I know. But think about what they actually mean operationally.

Fifty-five percent faster onboarding means a developer who took three weeks to be productive now takes nine days. Not sexy, but scale it: at a 200-person engineering organization with 20% annual turnover, you’re talking about thirty person-weeks per year that you’re not wasting on “where’s the deployment documentation” and “how do I check if my service is actually running.” You’re also losing less institutional knowledge because it’s not locked in someone’s head.

The 32% reduction in unplanned downtime is more interesting because it suggests the portal isn’t just documentation. It’s actively preventing failures. When developers can see service dependencies clearly, understand on-call rotations, check resource quotas, and validate configurations before pushing to production, they make different decisions. They don’t make changes at 4:45 PM on Friday because the portal shows three critical services depending on what they’re about to touch. They don’t accidentally spin up expensive compute because they can see costs in real time. It’s not magic. It’s just friction in the right place.

How to Actually Start Without Becoming a Yak-Shaving Project

Here’s where I see most teams get it wrong. They look at Backstage or Humanitec or Port, see that beautiful integrated experience, and think “we need that exact thing.” Then they spend six months customizing plugins and arguing about whether their service catalog should use auto-discovery or manual registration. A year later, they’ve got 40% adoption and a growing technical debt problem.

Start smaller. Actually smaller than you think you should. Your first portal doesn’t need to be Backstage. It can be a Kubernetes dashboard plus a Slack bot that shows deployment history plus a simple Markdown wiki. Build it in two weeks. Get it in front of developers. Watch what they actually ask for, not what you think they need. The developers who are frustrated with current tools will tell you exactly where the pain is.

Then, and only then, start thinking about consolidation. Maybe you do need Backstage at that point. Maybe you need something lighter. But you’ll know because your users will tell you, and you’ll have real feedback instead of a theoretical org chart saying “platform engineers should build a portal.”

The teams that pull this off well treat the portal like a product, not a project. Someone owns it. There’s a roadmap. Users file issues. You prioritize based on impact and complexity, not on what’s theoretically correct. That sounds obvious, but most internal tools get built with the attitude of “launch and maintenance.” A good portal deserves real investment and real attention, the same way any product serving your entire organization would.

The Actual Question You Should Be Asking

Platform engineering is real. Internal developer portals solve real problems. But the question isn’t whether you need them. It’s whether you’re ready to treat developer experience as a first-class concern in your organization. That means hiring people specifically focused on making developers faster, not just keeping infrastructure running. It means measuring their success by how fast developers ship, not by how few tickets they get.

If that sounds like a cultural shift as much as a technical one, you’re paying attention. Because it is. The tools matter less than the mindset.

What’s your current bottleneck for developers? Not the obvious one, but the real one you see in standup when someone’s frustrated. Tell me in the comments, or hit me on whatever social platform you pretend to check but actually check obsessively. I want to know what’s broken in your stack, because that’s usually where the best solutions start.

Platform Engineering Is Eating DevOps and Your Organization Isn’t Ready

Platform Engineering Is Eating DevOps and Your Organization Isn’t Ready

The Prediction That’s Already Becoming Reality

Gartner dropped a forecast in 2025 that should have set off alarm bells in every engineering organization: 80 percent of large software companies will have established platform engineering teams by 2026. That’s a jump from roughly 45 percent in 2023. That’s the kind of adoption curve you see when something stops being optional and starts being table stakes. The predictions are already showing up in hiring, compensation, and organizational restructuring across the industry.

Platform Engineering Is Eating DevOps and Your Organization Isn't Ready
Platform Engineering Is Eating DevOps and Your Organization Isn’t Ready

What’s remarkable isn’t that platform engineering is growing. It’s that most teams are treating this as a tooling problem when the real issue is organizational. You can buy the best Kubernetes distribution and deploy Backstage before breakfast, but if you haven’t sorted out who owns what and why, you’re building a faster way to fail.

The Numbers Don’t Lie, But They Do Mislead

The DORA 2025 State of DevOps Report published findings that sound like fiction if you’re still running the old DevOps playbook. Teams with mature internal developer platforms are deploying 2.4 times more frequently and experiencing 60 percent fewer change failures compared to organizations without centralized platform tooling. Those aren’t marginal improvements. Those are the kind of metrics that make CFOs pay attention and engineering leaders start asking uncomfortable questions about why their teams aren’t operating at that level.

But here’s where things get complicated. Those numbers describe organizations that have already crossed the chasm. They’ve built their platforms and aligned their teams around them. The real story isn’t in the deployment frequency metric. It’s in what had to happen organizationally to make those numbers possible. And that’s where most teams are stumbling.

The Adoption Problem Disguised as a Tooling Problem

Backstage, the open-source developer portal originally built at Spotify, has become the default standard for internal developer platform infrastructure. Over 3,200 organizations have adopted the CNCF Backstage project. That’s a staggering number for an open-source project. It signals real market demand and architectural validation. But adopting a tool is not the same as a successful platform engineering transformation. Not even close.

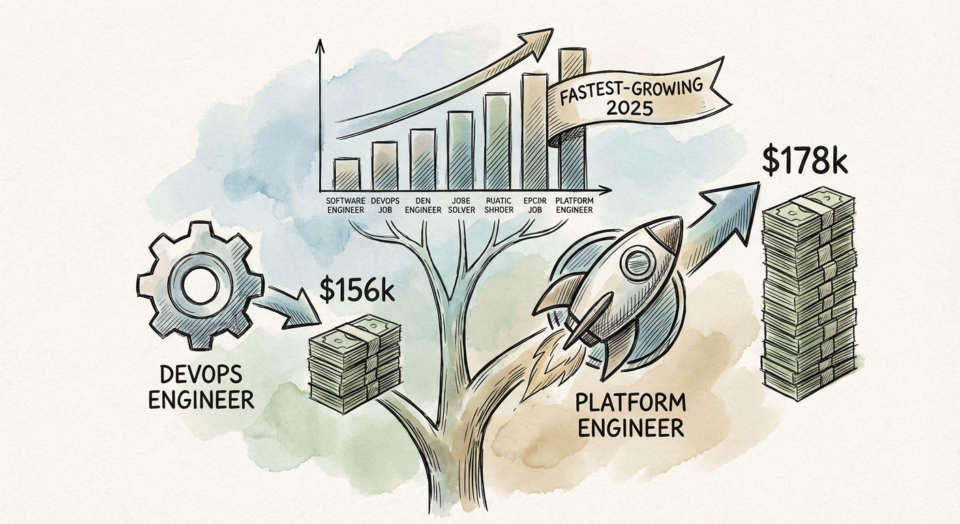
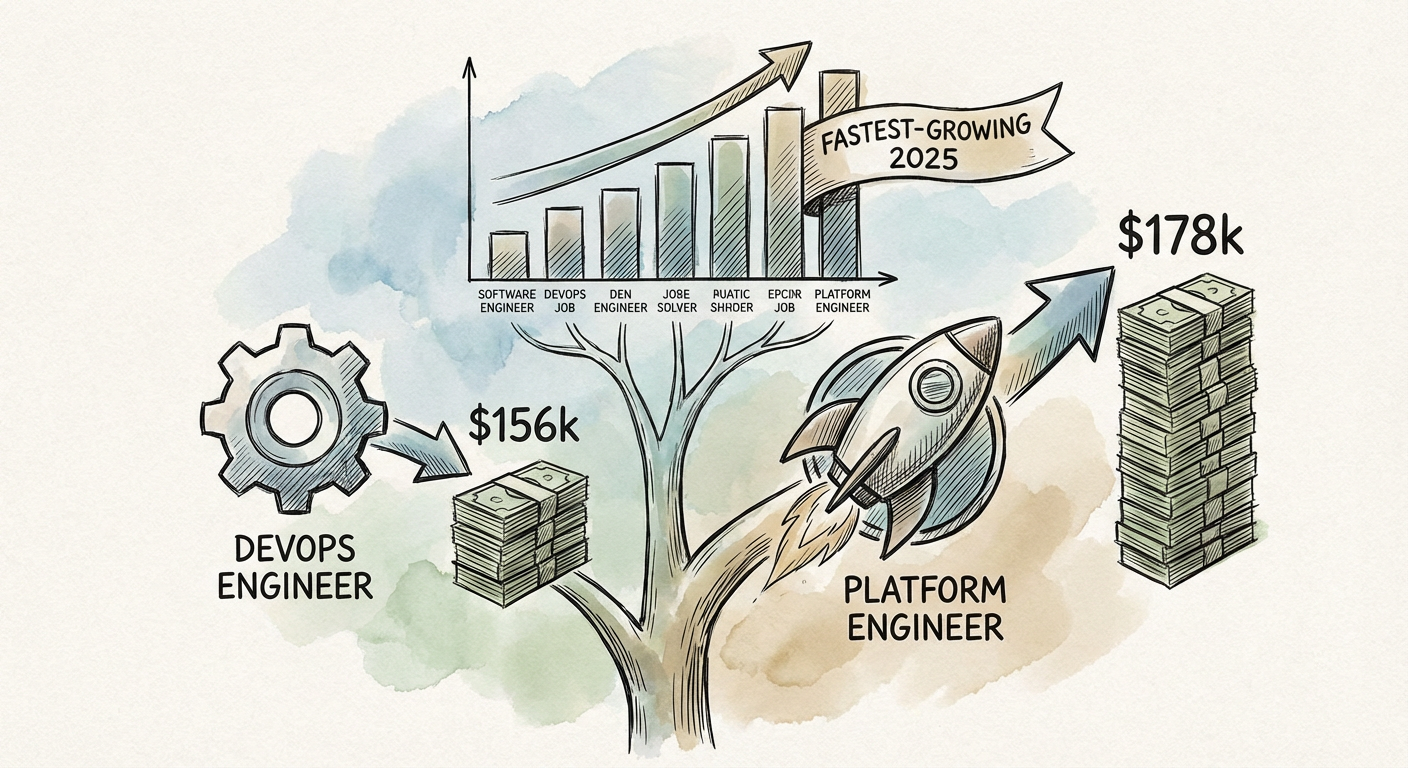
The job market is sending the same message in a different register. Platform engineer has cracked the top five fastest-growing job titles, with median compensation in North America hitting $178,000. That’s 14 percent higher than traditional DevOps engineer salaries. Companies are desperately hiring for these roles because they know what the data says about outcomes. The problem is that money can’t buy organizational alignment, and no number of senior platform engineers will fix a structure where nobody agrees on what the platform is supposed to do.

Why 67 Percent of Transformations Fail Before They Start

Puppet’s 2025 State of DevOps Report delivered the kind of finding that should prompt serious reflection in any organization attempting a platform engineering shift. Sixty-seven percent of companies cited internal team resistance and unclear ownership boundaries as their primary failure mode. Not Kubernetes. Not observability tooling. Not even the usual suspects of technical debt and legacy systems. It was people and structure.

This is where skepticism is warranted. We have decades of evidence that you can’t reorganize your way out of bad communication, and you can’t automate your way around unclear incentives. Platform engineering teams exist to serve developers, but if developers don’t understand what the platform does or how to use it, and if traditional DevOps and SRE teams view platform engineering as a threat to their turf, you’ve built the infrastructure for conflict, not velocity. The platform becomes a bottleneck wrapped in good intentions.

The organizations actually seeing those 2.4x deployment frequency gains have done something harder than picking infrastructure. They’ve made explicit decisions about who owns reliability, who controls deployment, who’s responsible for developer experience, and how those teams interact without friction. They’ve probably reorganized. They’ve definitely had uncomfortable conversations about what stays and what goes. They’ve made trade-offs between centralization and autonomy and documented those trade-offs so people understand the reasoning.

What This Means for Your Next Board Meeting

If you’re responsible for engineering outcomes in an organization with more than a few hundred developers, you’re facing a decision point whether you’ve framed it that way or not. The trajectory is clear. Platform engineering is becoming the dominant operating model, and lagging adoption will eventually create competitive disadvantage. But moving fast on platform engineering without addressing organizational structure is how you end up with an expensive tool that nobody wants to use.

Start with clarity on ownership. Build a small platform team with an explicit charter and clear interfaces to the teams they serve. Treat internal developer experience as a first-class metric alongside deployment frequency and change failure rate. If you’re looking at adopting tooling like Backstage, great. But sequence that after you’ve sorted out what problems you’re actually solving and who’s accountable for solving them. The technical part is almost always easier than the organizational part.

What’s your organization’s current state? Are you planning a platform engineering transformation, or are you already mid-transition and wondering why adoption isn’t tracking to plan? The pattern is becoming predictable enough that we should be able to learn from each other’s mistakes before making our own.

Google’s Willow Quantum Chip and the Encryption Race We’re Already Losing

The Benchmark That Broke the Internet’s Brain

In December 2024, Google DeepMind announced the Willow quantum chip, and the internet did what the internet does: it took a complex technical achievement and turned it into “quantum computer goes brrr.” But here’s the thing worth understanding. The Google Willow quantum chip announcement described a benchmark computation completed in under five minutes. The same calculation would take today’s fastest classical supercomputers roughly 10 septillion years. That’s not a typo. That’s 10 followed by 24 zeros.

Before your threat model alarm bells start ringing, let’s be precise about what this actually means. Willow doesn’t break encryption today. It doesn’t remotely threaten your infrastructure this morning. The benchmark is a narrow, carefully constructed problem designed specifically to showcase quantum advantage. It’s not a general-purpose supercomputer replacement, and it’s certainly not a practical attack vector against RSA-2048 or elliptic curve cryptography yet. What it is, though, is a very loud signal that quantum computing’s theoretical advantage is moving from “someday” into “sooner than we thought” territory.

Error Correction: The Unglamorous Problem That Actually Matters

The real story with Willow isn’t the benchmark number. It’s something quieter and more fundamental: Willow achieved below-threshold error correction across 105 qubits. If you’ve been following quantum computing for more than five minutes, you know that error correction is where the entire field has been stuck for years. Quantum states are fragile. They decohere. Qubits flip. Building more qubits without solving error correction just amplified the noise, not the capability.

What Willow demonstrated is that adding more qubits actually reduced errors rather than increased them. This is the first time a hardware platform has crossed that threshold. Think of it like owning a car where driving faster makes the engine more stable rather than more likely to blow up. In quantum computing terms, this is the moment where scaling starts to work the way the theory always said it should.

Why should you care about error correction if you’re managing infrastructure today? Because fault-tolerant quantum computing is the prerequisite for quantum computers that can run algorithms long enough to threaten modern encryption. A quantum computer with uncorrected error rates can barely run a useful algorithm before the noise drowns out the signal. A quantum computer with corrected errors can, in theory, run Shor’s algorithm against RSA keys. We’re not there yet, but we’re watching someone build the ladder one rung at a time.

NIST Draws the Line. Finally.

While Google was celebrating error correction milestones, NIST did something quieter but possibly more important for your actual job. In August 2024, they finalized the first three post-quantum cryptography standards. Not proposals. Not recommendations. Standards. The three are ML-KEM (from CRYSTALS-Kyber), ML-DSA (from CRYSTALS-Dilithium), and SLH-DSA (from SPHINCS+). These algorithms are designed to resist attacks from both classical and quantum computers. The NIST post-quantum cryptography standards announcement gives you the concrete migration target you’ve been waiting for.

What this means practically: you now have a defined migration path. These aren’t theoretical algorithms anymore. They’re vetted, tested, and officially recognized. Vendors will start shipping implementations. Your architecture teams can start planning. The conversation shifts from “should we think about this” to “when do we need to be done.”

The timeline got sharper when the NSA released Commercial National Security Algorithm Suite 2.0 in 2022 with a 2030 compliance deadline for national security systems. If you’re a federal contractor, a healthcare provider handling classified data, or any organization in the national security supply chain, this isn’t theoretical. This is a hard line. By 2030, post-quantum algorithms need to be the default. Your migration planning window is measured in months now, not years.

The Inventory Crisis Nobody’s Ready For

Here’s where the conversation gets uncomfortable. According to a 2025 Ponemon Institute survey, only 18% of enterprise security teams had begun a formal inventory of their cryptographic assets. Eighteen percent. Not “completed the migration.” Not “started testing.” Not even “made a strategic plan.” Begun a basic inventory.

This is the quiet disaster hiding behind the quantum hype. You cannot migrate something you don’t know you have. Cryptographic material is everywhere in modern infrastructure: TLS certificates, SSH keys, VPN configurations, HSM policies, firmware signing keys, code signing certificates, and a thousand other places most organizations have never fully mapped. It’s in legacy systems that haven’t been touched in five years. It’s in third-party integrations where the vendor controls the crypto stack. It’s embedded in network devices that haven’t been updated since the Bush administration’s first term.

The math is brutal. If you’re in the 18% that has started inventory, you’re ahead. If you’re in the 82% that hasn’t, you’re already behind. The NSA gave you until 2030. NIST gave you the standards. Google just demonstrated that quantum capabilities are advancing faster than most people’s threat models account for. None of that automatically buys you time if you’re still discovering cryptographic assets in June 2029.

What You Should Actually Do Monday Morning

Honest take: Willow is impressive and important, but it’s not tomorrow’s problem. It is, however, this year’s planning problem. Your organization needs to start the inventory work. Not because quantum computers are breaking into your data center next week, but because the migration window is real and finite and most organizations move slower than they think they do.

The practical steps are unglamorous. Catalog where cryptographic material lives across your infrastructure. Understand which algorithms are in use and which systems depend on them. Evaluate the post-quantum standards and how they perform in your specific environments. Test. Plan upgrade paths for systems that can’t be easily updated. Understand supply chain dependencies. None of this is exciting. All of it is necessary.

Willow is a milestone, not a crisis trigger. But crises don’t announce themselves politely. They show up when you weren’t ready, and readiness starts with knowing what you’re protecting and how you’re protecting it. If you haven’t started that conversation in your organization yet, start it this week. The quantum advantage is coming. Getting your infrastructure ready beforehand is the whole point.

OpenTofu vs. Terraform in 2026: The Fork Has Matured and the Decision Is No Longer Obvious

The Fork That Nobody Expected to Survive

I remember August 2023 like it was yesterday. HashiCorp announced they were moving Terraform to the Business Source License, and suddenly every infrastructure engineering team I knew was in a group chat asking variations of the same question: “Wait, we have to pay now?” The BSL announcement wasn’t technically a betrayal—licenses change, companies pivot, that’s business—but it felt like watching a friend you trusted make a decision that left you standing in the parking lot wondering if you’d been reading the same relationship.

Enter OpenTofu. The Linux Foundation got involved. A fork happened. And here we are in early 2026, staring at a scenario I genuinely did not expect to write about: OpenTofu isn’t the scrappy underdog project anymore. It’s become a credible, feature-leading alternative with development velocity that’s actually outpacing HashiCorp’s Terraform in several metrics. The decision matrix has shifted. The fork has matured. If you’re still on pure Terraform without even glancing at what’s happening across the fence, you might be leaving real capability on the table.

Where the Technical Lead Gets Interesting

Let me ground this in specifics, because general statements about forks are boring and usually wrong. OpenTofu shipped version 1.9 in late 2025 with provider-defined functions and native state encryption. Terraform’s current releases don’t have either of those features. Full stop. That’s not marketing spin—that’s a capability gap you can actually use right now.

The provider ecosystem has also reached critical mass. OpenTofu’s registry had crossed 2,000 mirrored providers by the beginning of this year. The GitHub repository sits north of 23,000 stars. More tellingly, contributor velocity metrics show OpenTofu committing code at a higher frequency than Terraform for several consecutive months through late 2025. This matters because it signals momentum, but also because bugs get fixed faster and features ship faster. When you’re managing infrastructure at scale, that velocity difference compounds.

What really tipped the scales for me personally was talking to three separate enterprises in the last six months who’d actually completed full migrations from Terraform to OpenTofu. Not pilots. Not test environments. Complete migrations. A Spacelift survey from 2025 found that 34% of infrastructure teams evaluating OpenTofu had finished full migrations, with another 28% partway through. That’s not marginal adoption. That’s material market movement.

The IBM Factor Nobody’s Talking About Enough

HashiCorp sold to IBM for 6.4 billion dollars in mid-2024. On the surface, that’s just a headline. Dig deeper and it’s a narrative inflection point. IBM’s product roadmap communications in the months since acquisition have been careful, measured, and conspicuously light on explicit commitments to maintaining Terraform’s open-source independence. When your major vendor gets acquired by a company known for monetizing enterprise software differently than startups do, infrastructure teams notice.

This is where licensing uncertainty enters the conversation. Pulumi released their State of Cloud Infrastructure report in 2025, and 41% of platform engineers cited IaC tool licensing uncertainty as a top-three risk factor for their 2025-2026 toolchain planning. That’s nearly half the market explicitly worried about stepping on a licensing landmine. OpenTofu, governed by the Linux Foundation and backed by the open-source community, doesn’t carry that risk profile. It can’t. That’s the entire reason it exists.

The Honest Trade-offs You Actually Need to Know

I’m not here to tell you OpenTofu is objectively better. That would be stupid and wrong. Terraform still has deeper market penetration, which means more third-party tooling integration, more blog posts when you’re stuck at 2 AM, and more people on call who already know how to operate it. Enterprise support, if you want to pay for it, is clearer with Terraform. Module ecosystem depth still favors Terraform, though that gap is narrowing monthly.

OpenTofu’s documentation is solid but not enterprise-brochure-level polished. The OpenTofu official documentation and changelog are genuinely comprehensive and well-maintained, but they read like documentation written by engineers for engineers. Terraform’s docs feel slightly more curated toward beginner audiences. If your team spans from infrastructure specialists to developers who touch Terraform once a quarter, that difference matters.

Ecosystem tooling like Terragrunt, Atlantis, and cloud-specific integrations are more mature on Terraform’s side simply because Terraform has had more years and more enterprise deployments. But none of these differences are permanent moats. In a fast-moving ecosystem, six months changes things. In a year, it changes everything.

What the Ground Truth Says

I’ve been in enough architectural decisions to know that the honest answer in early 2026 is this: if you’re greenfield, if you’re starting fresh, the calculus between Terraform and OpenTofu is not lopsided anymore. It genuinely depends on whether your risk tolerance leans toward “vendor stability” or “license stability.” Both are legitimate concerns. They’re just different concerns now.

If you’re on existing Terraform, you don’t need to panic-migrate. Your code works. Your team knows the tool. Moving for the sake of moving is cargo-cult engineering. But running a limited pilot migration with a new workload or a team that’s building fresh infrastructure? That’s legitimate experimentation. The fork has matured to the point where that experiment actually yields useful data instead of just producing frustration.

The maturation of OpenTofu means your answer to “Terraform or OpenTofu?” in 2026 is no longer “obviously Terraform.” It’s “what are your constraints and what does your risk matrix look like?” That’s more work to think through than a simple answer, sure. But it’s also more honest. The fact that we’re even having this conversation is proof that the fork succeeded in doing what it set out to do: create a real alternative.

If you’ve got experiences from the trenches with either tool, or if you’ve been through a migration yourself, I’d genuinely like to hear what you’ve learned. The landscape is shifting fast enough that data from real deployments matters more than analyst reports right now.

Why GitHub Copilot Workspace Still Can’t Replace a Senior Engineer’s Judgment in 2026

Why GitHub Copilot Workspace Still Can’t Replace a Senior Engineer’s Judgment in 2026

The Workspace Promise and the Reality Check

Last November, I watched GitHub Copilot Workspace hit general availability and felt that familiar flutter of excitement mixed with skepticism. Here was a tool promising to take you from issue description to merged pull request without ever leaving your browser. Eighteen months ago, that sounded like science fiction. Now it’s here, and over 1.8 million developers are actively using it within the first six months. The hype machine was real, and honestly, some of it was deserved.

Why GitHub Copilot Workspace Still Can't Replace a Senior Engineer's Judgment in 2026
Why GitHub Copilot Workspace Still Can’t Replace a Senior Engineer’s Judgment in 2026

But here’s what I’ve learned after two and a half decades of shipping code: tools that promise to eliminate your job are usually just moving the problem somewhere else. Rarely eliminating it. Copilot Workspace is genuinely useful. I’m not being cagey about that. But I’ve also spent the last few months watching it fail in ways that confirm something important: the judgment that separates a senior engineer from a productivity suite is not about generating code faster. It’s about knowing which code shouldn’t be written in the first place.

Illustration for Why GitHub Copilot Workspace Still Can't Replace a Senior Engineer's Judgment in 2026
Illustration for Why GitHub Copilot Workspace Still Can’t Replace a Senior Engineer’s Judgment in 2026

Where the Logic Errors Hide

A Stack Overflow survey from late 2025 found that 76% of developers using AI coding tools were still spending substantial time fixing logic errors in code adjacent to production systems. That number should scare you a little. It should also not surprise you at all. I’ve been watching this play out in pull request reviews for months now.

The AI understands syntax. It understands patterns. What it doesn’t reliably understand is the business logic that makes your specific system tick. Last quarter, I caught Copilot Workspace generating a perfectly valid sorting algorithm in an ecommerce pipeline that would have nuked our customer tier validation logic. The code was syntactically flawless. It would have compiled. It would have passed basic unit tests. But it made an assumption about data immutability that only holds true in exactly three cases out of the twelve different execution paths in our actual system.

A senior engineer spots that because they’ve traced those execution paths before. They’ve debugged the weird edge case at 3 AM when a customer’s quarterly order didn’t process right. They know where the landmines are buried. Copilot Workspace generates beautiful code in the sunny scenarios. Real systems, with all their Byzantine complexity, trip it up every single time.

The Code Churn Problem Nobody Wants to Admit

Here’s the data point that actually keeps me up at night. GitClear published research in early 2026 showing that AI-assisted codebases had a 41% increase in code churn compared to their pre-AI baselines. Code churn means rewriting code that was recently committed. It means instability. It means that thing you thought was done is getting rewritten within weeks because it didn’t work the way everyone assumed it would.

When I first read that report, I felt validated in a way I didn’t expect. My team’s churn metrics had ticked up since we started leaning more heavily on Copilot Workspace. We assumed it was because we were moving faster, shipping more, breaking more things. Turns out we were just rewriting more things. There’s a difference, and it’s an expensive one.

The pattern I’ve observed is this: Copilot Workspace helps you write code 30% faster. But if that code is going in the wrong direction strategically, you’ve just accelerated the wrong journey. Half a senior engineer’s job is knowing when to step back and say “wait, are we solving the right problem?” That’s not a code generation question. It’s an architecture question. A judgment question.

Why the Competition Is Getting Scary

I need to be honest about something. The bar for what AI can do is rising faster than I expected. Anthropic released Claude 3.7 Sonnet in February 2026 with an extended thinking mode that hit a 70.3% resolution rate on SWE-bench Verified. That’s the kind of benchmark that makes you sit up in your chair. It outperforms GPT-4o on complex software engineering problems. The gap between “good at boilerplate” and “good at reasoning about complex systems” is closing.

Does that terrify me? Not entirely. It should make me more thoughtful. These tools are genuinely getting better at the kinds of problems that require actual reasoning. But raw benchmark performance on standardized tests doesn’t translate neatly to production judgment. I can throw a complex problem at Claude 3.7 in extended thinking mode and get a legitimately impressive solution. Then I deploy it to a system with three years of technical debt and custom middleware, and suddenly we’re talking about something completely different.

What Senior Judgment Actually Looks Like Now

So what does a senior engineer do when the tooling can generate code faster than they can think about whether the code should exist? Honestly, your job gets more interesting. You stop being a code generation unit. You become a filter, a strategist, and a remorse prevention specialist.

I’ve started using GitHub Copilot Workspace documentation as a productivity boost for the 40% of tasks where the requirements are crystal clear and the domain is well-understood. Then I spend my brainpower on the other 60%. That’s where I’m looking at three competing architectural approaches and understanding why we’re choosing one. That’s where I’m reading the code someone generated and asking “what assumptions does this make about our data flow?” That’s where I’m catching the thing that would have broken in production six weeks from now.

The GitClear 2025 AI Code Quality Report showed that the problem wasn’t the tools themselves. It was the judgment gap. Teams that succeeded with AI-assisted coding had senior people doing code review. Teams that just cranked out code and merged it saw quality degradation. That’s not a tool problem. That’s a process problem.

In 2026, being a senior engineer means knowing when to use Copilot Workspace to move fast and when to think slowly. It means recognizing that just because you can generate a solution in five minutes doesn’t mean you should deploy it in five hours. It means having the confidence to say “this code looks correct but I’m not sure it’s right” and digging deeper. No tool can do that for you. That’s judgment, and it’s never been more valuable.

What’s your experience been with this? Have you caught something that looked fine but would have exploded in production? I’d genuinely like to hear where your team is seeing the gaps.

AWS re:Invent 2025 Takeaways: Why Amazon’s ‘Graviton4 Everywhere’ Push Is Forcing a Real Conversation About ARM in Production

AWS re:Invent 2025 Takeaways: Why Amazon’s ‘Graviton4 Everywhere’ Push Is Forcing a Real Conversation About ARM in Production

The Uncomfortable Truth: ARM Adoption Just Crossed a Threshold

AWS walked on stage at re:Invent 2025 and dropped a number that should have made every infrastructure team sit up straighter in their chairs. Graviton4-based instances now power over half of all new EC2 instance launches within AWS’s own internal infrastructure. Not AWS customers. AWS itself. That’s not marketing noise—that’s the cloud provider voting with its own wallet, running its own services on silicon it controls. It’s the kind of signal that typically precedes a genuine market shift, the sort of thing you see a few years before everyone else is forced to follow.

AWS re:Invent 2025 Takeaways: Why Amazon's 'Graviton4 Everywhere' Push Is Forcing a Real Conversation About ARM in Production
AWS re:Invent 2025 Takeaways: Why Amazon’s ‘Graviton4 Everywhere’ Push Is Forcing a Real Conversation About ARM in Production

But here’s where skepticism earns its keep. We’ve seen AWS push proprietary technology before. Sometimes it works spectacularly well. Sometimes it creates friction that quietly haunts you at 2 AM when a critical dependency won’t compile on the new architecture. The real story isn’t whether Graviton4 is technically sound—the benchmarks are genuinely impressive. The story is that ARM adoption has crossed from “interesting option” to “you probably need to deal with this now,” and the industry isn’t quite ready to admit how messy that transition actually is.

Illustration for AWS re:Invent 2025 Takeaways: Why Amazon's 'Graviton4 Everywhere' Push Is Forcing a Real Conversation About ARM in Production
Illustration for AWS re:Invent 2025 Takeaways: Why Amazon’s ‘Graviton4 Everywhere’ Push Is Forcing a Real Conversation About ARM in Production

The Performance Economics Actually Work—When You Do the Math Correctly

Let’s talk price-performance, because that’s where Graviton4’s real advantage lives. AWS published benchmark data in late 2024 showing up to 30% better price-performance compared to equivalent x86-based instances for compute-intensive workloads. Thirty percent. In cloud infrastructure, that’s not a rounding error—that’s the difference between a budget that gets approved and one that gets questioned. That’s enough to move databases, enough to shift how you right-size your clusters, enough to make the CFO actually listen when you propose an infrastructure rewrite.

The catch, and there’s always a catch, is that “compute-intensive workloads” doing heavy lifting in languages that are well-optimized for ARM is not the same universe as your general-purpose application fleet. Run a standard Python web service with lots of system calls and I/O wait? The gains compress significantly. Run a data processing pipeline written in Go that hammers CPU relentlessly? Suddenly you’re seeing the full 30% number materialize on your bill. The economics work, but they work selectively. That matters more than AWS’s press releases suggest.

What actually drives adoption at scale isn’t the best case scenario. It’s the good-enough case scenario combined with management pressure. When your cloud bill is your second-largest operational expense and a competitor demonstrates they’ve cut theirs through Graviton migration, the economics stop being optional. That’s where we are now. The AWS Graviton4 instance documentation has gone from “nice reference material” to “required reading for anyone scoping infrastructure work.”

The Adoption Numbers Are Real, But the Devil Is Actually in Production

The CNCF Annual Survey 2025 reported that 38% of respondents now run at least one ARM-based workload in production, up from 21% in 2023. That’s a dramatic swing. That’s not early adopters anymore. That’s the mainstream starting to move. And yet, somehow, every infrastructure conversation I’ve had in the past six months includes at least one story about an ARM migration that went sideways—not catastrophically, but in that specific, infuriating way where everything mostly works except for one thing that breaks silently.

The developer experience tells you where the real friction lives. Docker’s official multi-platform build tooling reported a 60% increase in multi-architecture image builds in 2025. That sounds great until you realize what it actually means: every developer building container images is now either explicitly thinking about ARM compatibility or will be soon. That’s a tax on velocity. It’s not a massive tax—most modern build systems handle it—but it’s a tax nonetheless. You can’t ignore it.

What troubles me more than the build complexity is what happens after the image ships. Datadog documented a particularly nasty class of failures in their engineering blog in 2025: third-party C-extension Python packages that still lack pre-built ARM wheels. Your Lambda migration to Graviton looks clean until runtime, when a package import silently fails and your handler returns a cryptic error. No build failure. No test failure. A production failure wrapped in enough abstraction layers that debugging takes three times longer than it should. These are the stories that make engineers cautious about ARM adoption, regardless of what the benchmark charts say.

Compatibility Is Still the Real Battlefield

The uncomfortable part of the ARM conversation isn’t the processor architecture itself. ARM is genuinely well-designed. The uncomfortable part is that we have twenty years of software ecosystem built assuming x86. Rewriting the world takes time. I’ve watched organizations commit to Graviton migrations that went smoothly for 80% of their workloads and then spent three months tracking down which legacy monitoring agent or database driver or observability library simply doesn’t have ARM support, or has it but with subtle behavioral differences that only emerge under specific load patterns.

This isn’t an indictment of Graviton or ARM in general. It’s an acknowledgment that ecosystem migration is genuinely hard. The software vendors who built solid, well-maintained ARM support early are winning quietly. The ones who haven’t bothered are becoming blockers. And the ones in the middle—the abandoned open-source projects, the legacy vendor software running in containers, the internal tools nobody’s updated in five years—those become the migration stoppers that nobody wants to discuss in planning meetings.

What This Actually Means for Your Infrastructure Decisions

The takeaway from re:Invent 2025 isn’t that you must migrate everything to Graviton immediately. The takeaway is that ARM in production has stopped being optional in the near-to-medium term. Half of AWS’s own new launches are Graviton-based. 38% of the industry is already running ARM workloads in production. The momentum is real.

But momentum doesn’t eliminate friction. Start with workloads where you control the full stack. Start with containerized services where you can test and validate multi-architecture builds. Invest in understanding where your dependencies actually stand on ARM support. And be honest with yourself about the operational tax—the extra monitoring complexity, the additional deployment testing, the dependencies you’ll need to patch or replace. That honesty converts a migration from a disaster waiting to happen into a managed project with reasonable scope.

The 30% price-performance wins are real. The industry adoption numbers are real. The compatibility headaches are also real. The question isn’t whether ARM belongs in your infrastructure anymore. The question is how you manage the transition thoughtfully instead of getting blindsided by it later. What’s your team’s current posture on ARM workloads? Are you testing multi-architecture builds, or do these re:Invent announcements represent your first real push to think about it seriously? I’d be genuinely interested in what friction points you’re hitting in your own environments.

Cursor 0.45 and the Rise of the ‘Agentic IDE’ — I Spent 30 Days Letting AI Drive and Here’s What I Learned

Cursor 0.45 and the Rise of the ‘Agentic IDE’ — I Spent 30 Days Letting AI Drive and Here’s What I Learned

The Moment Everything Shifted

Three years ago, I would have laughed at the idea of an IDE that codes for me. Not a laugh of derision, exactly—more the tired chuckle of someone who’s seen enough failed automation dreams to know better. But Cursor’s Agent mode in the 0.45 release did something I genuinely didn’t expect: it made me want to stop driving the keyboard.

Cursor 0.45 and the Rise of the 'Agentic IDE' — I Spent 30 Days Letting AI Drive and Here's What I Learned
Cursor 0.45 and the Rise of the ‘Agentic IDE’ — I Spent 30 Days Letting AI Drive and Here’s What I Learned

The shift wasn’t incremental. It was a phase change. When you can hand your IDE a task—”refactor this authentication module to use OAuth2, update all the imports, run the tests, and fix whatever breaks”—and watch it execute multi-step workflows without asking you for clarification between each step, something fundamental changes about how you relate to the work. I’m not talking about autocomplete. I’m talking about actual autonomy.

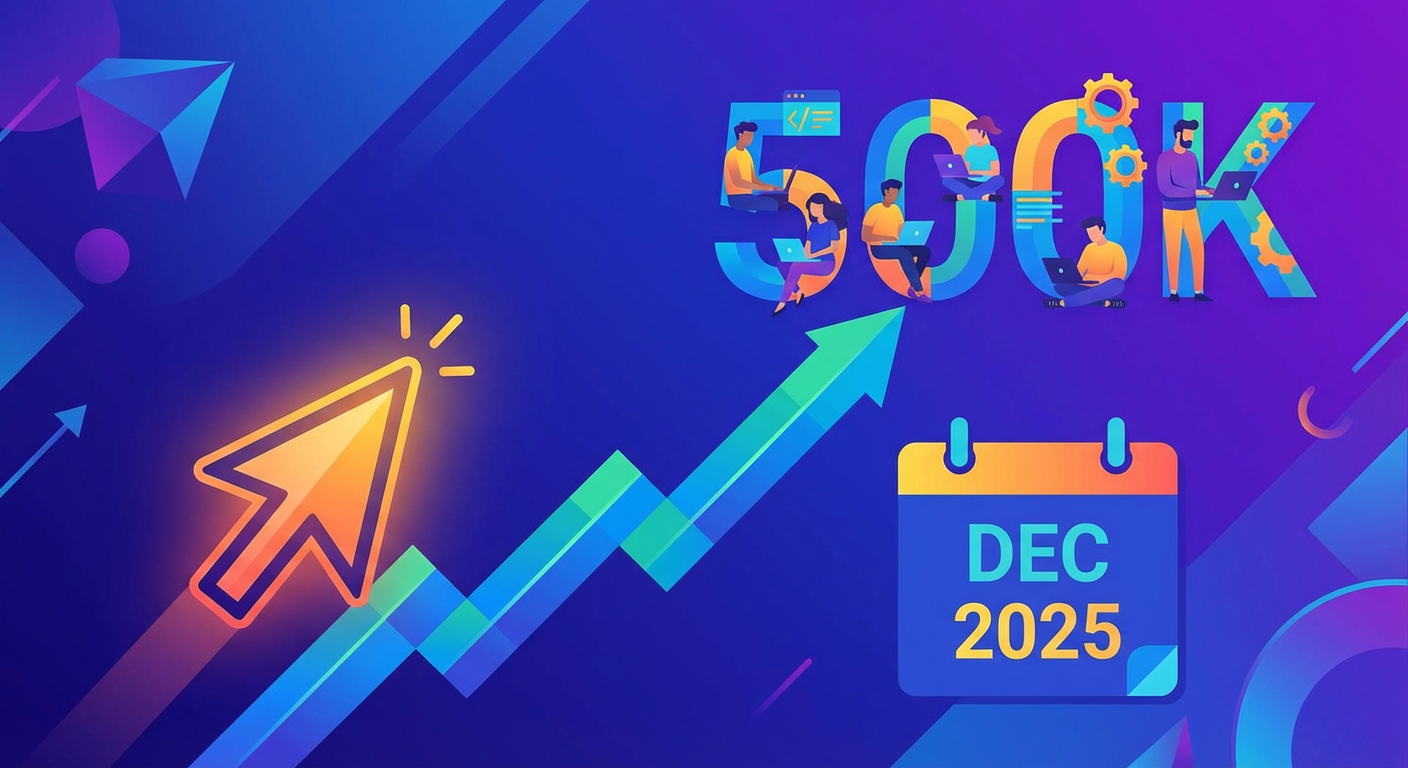
Cursor crossed half a million paying subscribers sometime in late 2025, which is the kind of growth trajectory that usually takes enterprise tools a decade to achieve. That number matters because developers have collectively decided this thing is worth paying for instead of using the free version.

Illustration for Cursor 0.45 and the Rise of the 'Agentic IDE' — I Spent 30 Days Letting AI Drive and Here's What I Learned
Illustration for Cursor 0.45 and the Rise of the ‘Agentic IDE’ — I Spent 30 Days Letting AI Drive and Here’s What I Learned

What Happens When Your IDE Gets Opinions

I spent a month actually trusting the agent to make decisions. Not babysitting it. Not reviewing every keystroke. Actually trusting it. And here’s where I’ll be honest: it’s unsettling in ways that surprised me.

The MIT research from their Computer Science and AI Lab confirmed something I felt viscerally—developers using agentic environments complete unfamiliar tasks roughly 55% faster. That’s not marginal improvement. That’s genuine acceleration. But they also found that the cost of that speed is a 22% increase in security-relevant code patterns that require human review. Translation: your AI IDE is faster, but it’s also writing code that demands more scrutiny.

This isn’t a bug. It’s a tradeoff, and an honest one. The agent doesn’t have the contextual knowledge or risk appetite that a senior engineer carries after years of incident reports and post-mortems. It sees the problem and the most direct solution. You see the problem and every way it could bite you in production. Both perspectives matter.

The Competitive Response and What It Means

Microsoft didn’t sit idle. They watched Cursor’s trajectory, saw the Pragmatic Engineer survey showing 41% of senior engineers at top-tier companies had switched from VS Code to Cursor, and accelerated their own agenda hard. By February 2026, Copilot Workspace had agent mode in general availability across VS Code, complete with its own multi-file editing and autonomous iteration capabilities.

What’s interesting, and what I suspect will matter more in retrospect, is that both products are converging on the same architectural philosophy: the IDE as a reasoning entity, not a glorified autocomplete. That convergence suggests we’re not in a temporary trend. We’re watching a genuine shift in what IDEs are meant to do.

The Cursor changelog and Agent mode docs read like a product team that knows exactly what they’ve built. There’s no pretense here. No “AI will replace developers” messaging. It’s pragmatic: here’s what the agent can do, here’s where it needs human judgment, here’s how to tune it for your workflow.

The Friction Points That Matter

After 30 days, I’ve hit the ceiling on what I’d entrust to pure autonomy. The agent excels at deterministic tasks—refactoring, adding logging, writing boilerplate, fixing obvious test failures. It struggles with architectural decisions, tradeoff analysis, and anything that requires understanding business context.

More importantly, it sometimes confidently generates code that’s technically correct but philosophically wrong for your system. I watched it suggest a perfectly functional implementation that violated patterns we’ve used across fifty services. The agent had no way to know that context. It just saw the problem and solved it.

This is where the real skill emerges. The valuable engineer in an agentic IDE world isn’t the one who can type fast or remember API signatures. It’s the one who can decompose problems well enough for an agent to handle the execution, then review what comes back with enough domain knowledge to catch the subtle mistakes that no test suite will surface.

What I Actually Believe Now

I went into this month as a skeptic. I’m coming out as a believer, but not in the way Silicon Valley wants you to believe. I’m not convinced that agentic IDEs will make everyone a 10x engineer. I am convinced they’ll make thoughtful engineers 10x more focused on what only humans can do—design, tradeoff analysis, judgment calls, and the second-order thinking that keeps systems resilient when reality deviates from assumptions.

The tool is genuinely useful. The speed increase is real. And the security tax is real too. If you’re still on the fence, spend a week with Agent mode focused on refactoring tasks only. Don’t hand it architectural decisions yet. Feel how it thinks. Then decide if the tradeoff makes sense for how you work.

The curve is steep right now, but it’s stabilizing. What comes next isn’t about who builds a better autocomplete. It’s about who builds the best tools for humans to direct and validate autonomous agents. I’m curious what you’ve found in your own experience. Hit me up on Twitter or drop a note—I’m genuinely interested in where the friction points are for other teams.